Built by infrastructure engineers who hit the vendor lock-in wall
ZML started when Steeve and Ana spent weeks rewriting a production inference pipeline every time GPU supply changed. There had to be a better way.
Hardware should be a runtime decision, not a design constraint
We believe the best ML infrastructure teams should spend their energy on models and data pipelines, not on accelerator vendor politics. ZML is our answer: a dispatch layer that keeps your inference stack hardware-agnostic by design.
When GPU supply tightens, prices spike, or a new accelerator generation ships, ZML lets you adapt without touching your application code. The routing decision happens at the infrastructure layer, where it belongs.
Independently funded. Paris, 2025.
The team
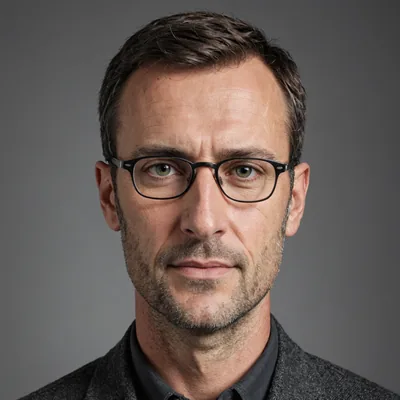
Steeve Morin
CEO & Co-Founder
Steeve spent years building distributed inference systems and cloud infrastructure for production ML workloads. He started ZML after watching teams repeatedly lose weeks to accelerator migrations that should have been invisible.
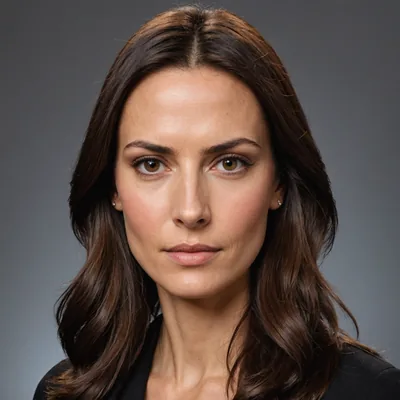
Ana Petrov
CTO & Co-Founder
Ana designs ZML's core dispatch engine. Her background is in systems engineering for high-throughput serving pipelines at compute-constrained scale, where accelerator flexibility is a survival requirement.
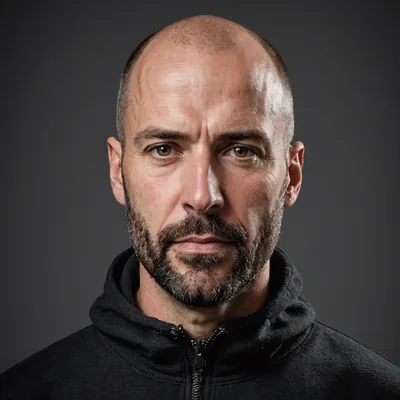
Marcus Webb
Head of Inference Engineering
Marcus has spent his career working across NVIDIA and AMD toolchains, tuning ML systems performance at the dispatch layer. He owns ZML's accelerator compatibility matrix and routing policy language.
Find us
-
Address
5 Rue de Mogador, 75009 Paris, France
-
Email
-
Phone
+33 1 40 82 71 00
ZML is an independently funded company. We are actively working with ML infrastructure teams running mixed accelerator clusters. If you want to run heterogeneous inference without rebuilding your pipeline every hardware cycle, reach out.